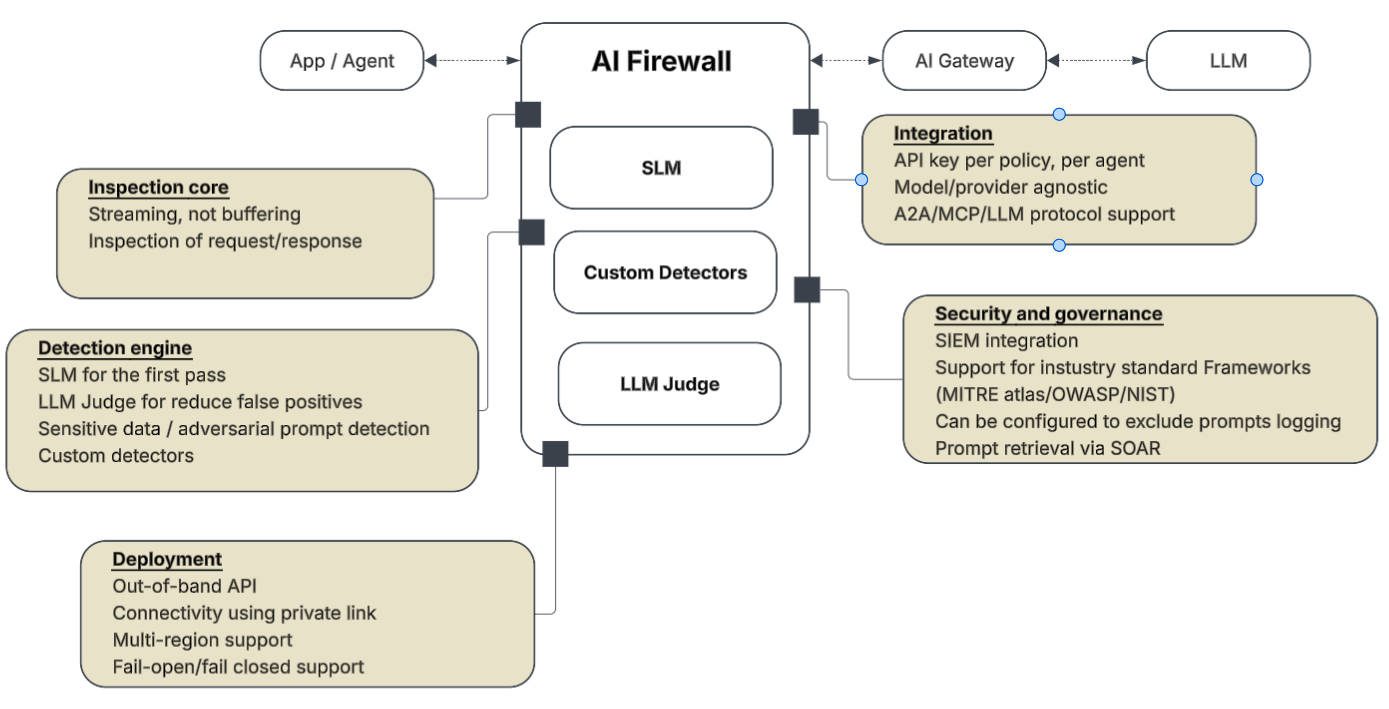
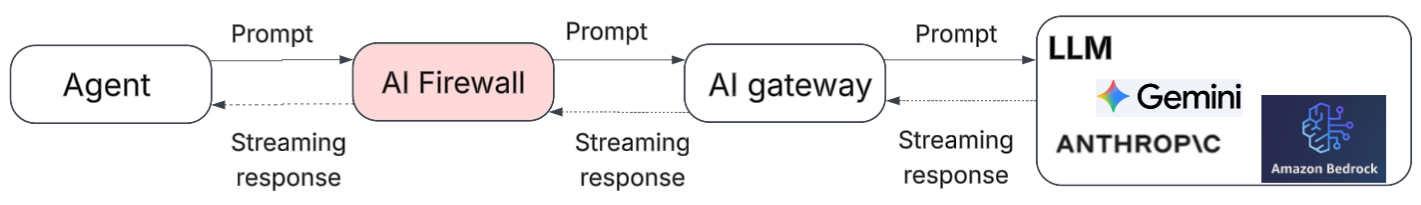
Anatomy of an AI firewall

Streaming support

The AI firewall should not buffer the response from the LLM but rather support streaming of the response from the LLM.
As you can see in the below screenshot, the output of the prompt “Describe the TLS handshake process in 400 words”(left side) is streaming in frames(right side).
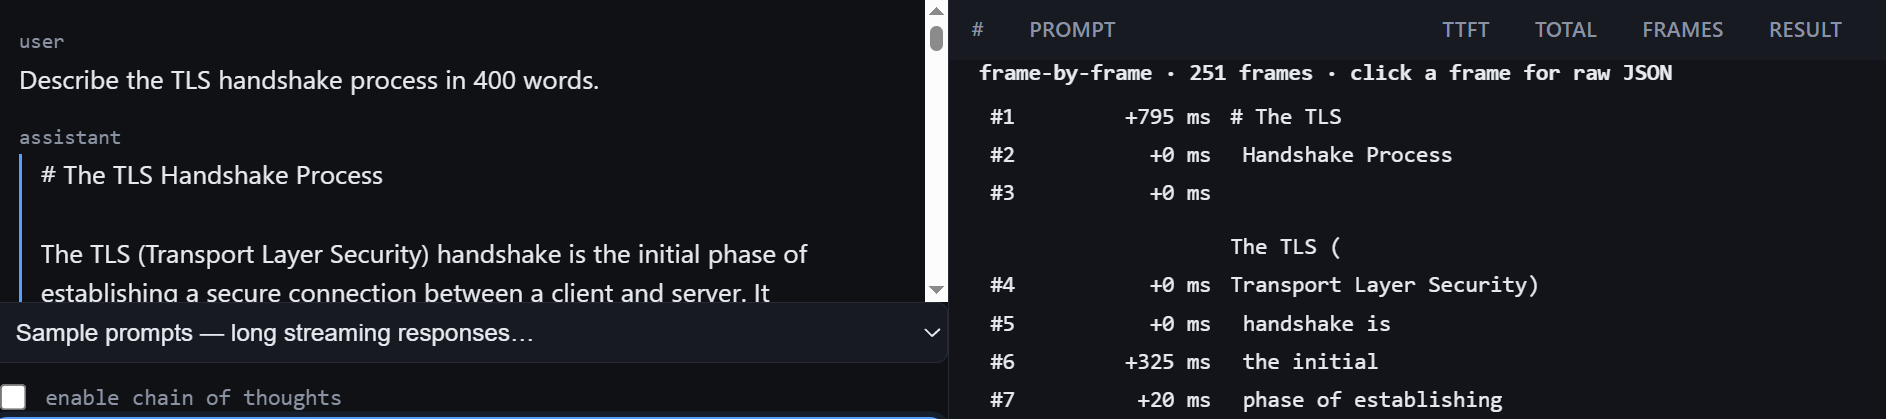
Zooming in – each frame is a genuine streaming chunk
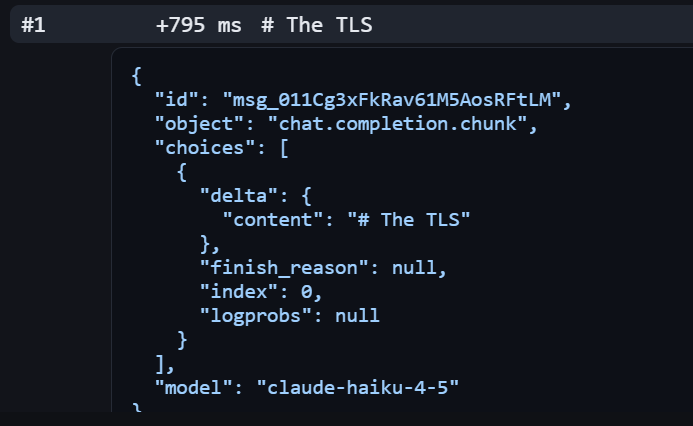
AI firewall should be able to show below metrics :

MeasurementWhat it is
TTFTTime to first token. What the user waits before the answer starts moving.
TTFBTime to first byte off the wire, just ahead of TTFT.
TotalStart to last token, the whole response.
FramesHow many chunks the response arrived in. Spread out means streaming, bunched at the end means buffered.
Model timeThe LLM’s own generation time. Reported by the AI gateway.
AI Gateway timeThe AI gateway’s overhead. Reported by the gateway.
Firewall processing*TTFB − (model + gateway)
The firewall’s slice. Inspection plus the network path to its edge, not CPU alone.

*Please note :
When the AI firewall blocks a prompt, it never reaches the AI gateway or the model – so all the time taken is by the AI firewall itself.
When the AI firewall does not block a prompt, the prompt goes through the AI gateway and then model and response comes back through same channel back.
An industry standard AI gateway includes the response headers noting the time taken by the upstream LLM and the AI gateway itself. Those response headers can be used by the AI firewall to calculate total time by the firewall.

Inspect ahead, cut before release. For the responses, It should catch a violation mid-stream and kills it before the bad part reaches the screen.

Both directions, separately:
Input and output are two inspections. Should be able to configure both or either,

Detection Engine

SLM for the first pass
A small language model should screen every request first. It’s fast and cheap enough to sit inline without wrecking latency.
Teach the SLM the domain specific constructs
The small language model should be trained on domain-specific constructs so it doesn’t throw false positives on legit prompts. For example, “Foley” reads like a person’s surname, but in a clinical note it’s a catheter. The model should understand the context, not just the word. And if it still flags a false positive, that’s where the LLM judge catches it.

Open term sources to train on:

* **Healthcare:** SNOMED CT and RxNorm, via the NLM’s UMLS.
* **Finance:** FIBO, from the EDM Council.

LLM judge to confirm
When the small model flags something which could be a false positive, it should escalate that one request to a bigger LLM judge to confirm. That way you only pay for the judge on the suspicious slice, not on every call.

Custom detectors
You should be able to add your own detectors, not just rely on the built-in ones. Sooner or later you’ll need to catch something the vendor never shipped. For example, quicly build a regex to detect something or exclude something without changing the SLM.

Configure the sensitivity of detection of SLM :
Should be able to configure the sensitivity of SLM to avoid false positives.

Named threat classes:
The firewall should name what it actually detects, so nobody waves it off as “AI stuff” – prompt injection, jailbreaks, PII and data exfiltration, tool and agent abuse.

Deployment

API key based access per agent
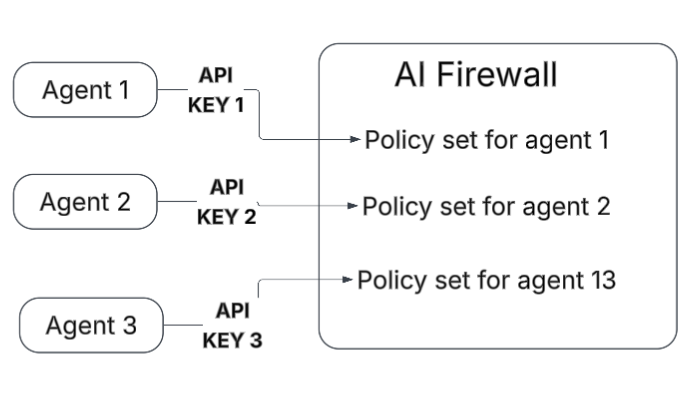
Inline to block. The firewall should be able to sit inline, right in the request path, so it can actually stop a bad prompt or response before it goes through.

Out-of-band / API based option.
It should also support an out-of-band mode, where it inspects a copy of the traffic off to the side. This adds no latency and won’t take your traffic down if it fails, but it can only alert, it can’t block.
https://guptaashish.com/2026/06/22/out-of-band-ai-inspection-the-missing-piece-in-cloudflares-ai-security-stack/

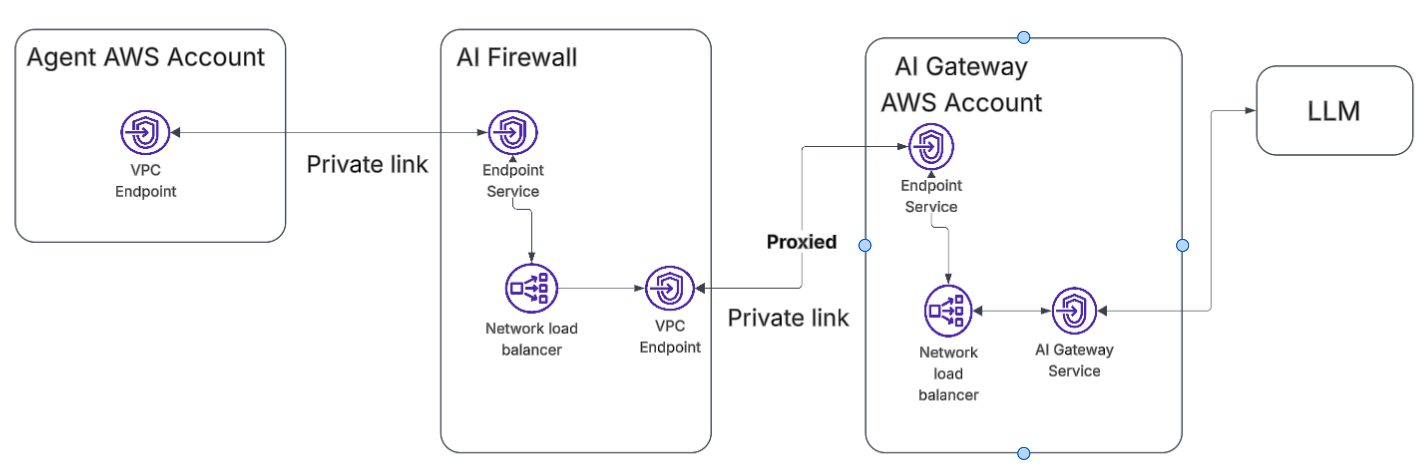
No forced public egress
For client data, the traffic should never leave to the public internet. The firewall should run inside your own cloud, or connect over a private link.
Fail-open vs fail-closed
You should be able to choose what happens when the firewall is unreachable. Does the traffic pass through, or does it get blocked?

Multi-AZ and multi-region
The firewall should run across multiple availability zones and regions.

Security and Governance

Metadata-only logging by default
The firewall should log only the metadata by default and keep the prompt and response content out, because that content can carry client PII. You turn on the full content only when you have a reason to.

Fast retrieval into SOAR
When a detection fires, you should be able to pull that prompt and response straight into your SOAR workflow, so the analyst can see exactly what triggered it and investigate right away.

Analysis time per request
The firewall should log how long it took to inspect each request, so you can prove you are inside your latency budget and catch it when it starts to drift.

Every detection mapped to a framework
A detection should never read as just “blocked.” When the firewall catches a prompt injection, it should tag it as OWASP LLM01. A jailbreak, a data exfiltration attempt, a tool-abuse attempt, each one should carry its label from MITRE ATLAS, the OWASP LLM Top 10, or the NIST AI RMF. That is what lets you report coverage to risk and compliance, and it is what makes the whole thing auditable.
Out-of-Band AI Inspection: The Missing Piece in Cloudflare’s AI Security Stack

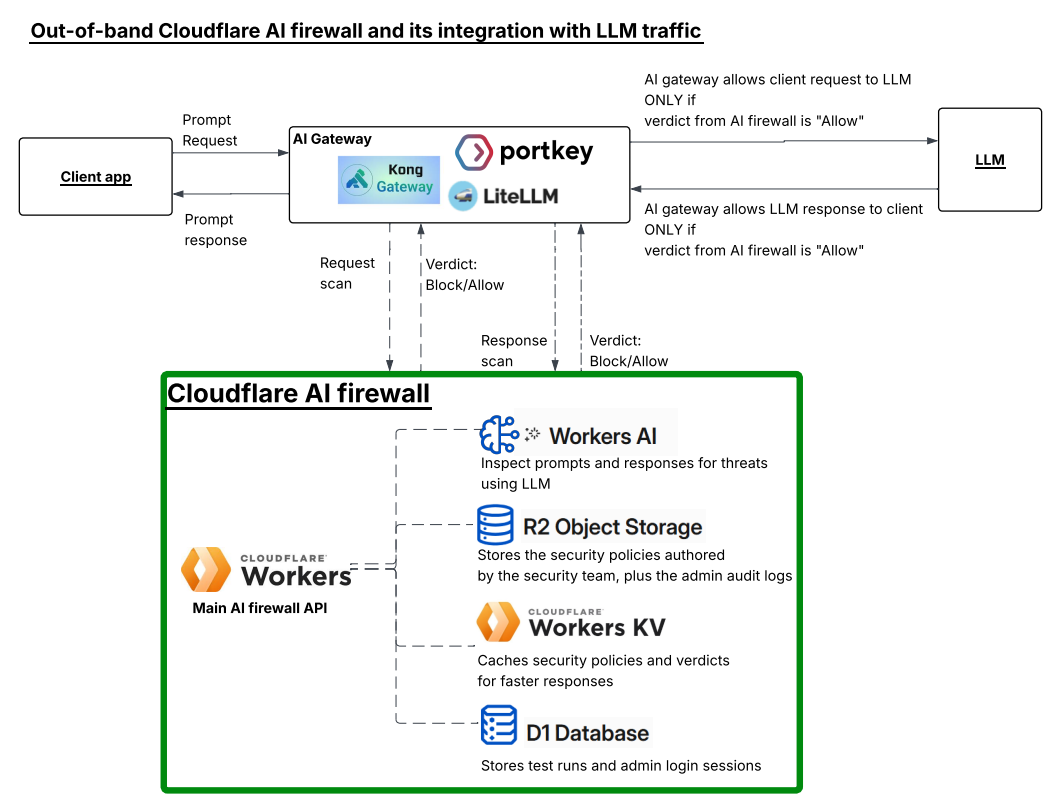
Cloudflare runs at massive scale and sits close to most of the internet, which makes it a natural place to inspect prompts. It can already catch injection, PII, and unsafe topics, so the detection engine is there. At the time of writing this, one thing it does NOT offer is an out-of-band verdict, an endpoint your own gateway can call to ask if a prompt is safe. Every path inspects inline, tied to the traffic flow. So I built a small proof of concept on Cloudflare’s own primitives to see what a native version of an out-of-band Cloudflare AI firewall might look like.

Cloudflare AI Gateway competes with Kong AI and LiteLLM. But an out-of-band firewall complements any gateway, not replaces it. That opens the market to every company that already has one.

What is an AI firewall

An AI firewall inspects prompts and responses in real time. It catches injection, jailbreaks, and PII leakage before they reach your LLM. Out-of-band means you call it as a separate API, off to the side of your model path. You send it a prompt, it sends back a verdict. That is the whole idea, and it is what lets you protect any gateway, not just traffic routed through Cloudflare.

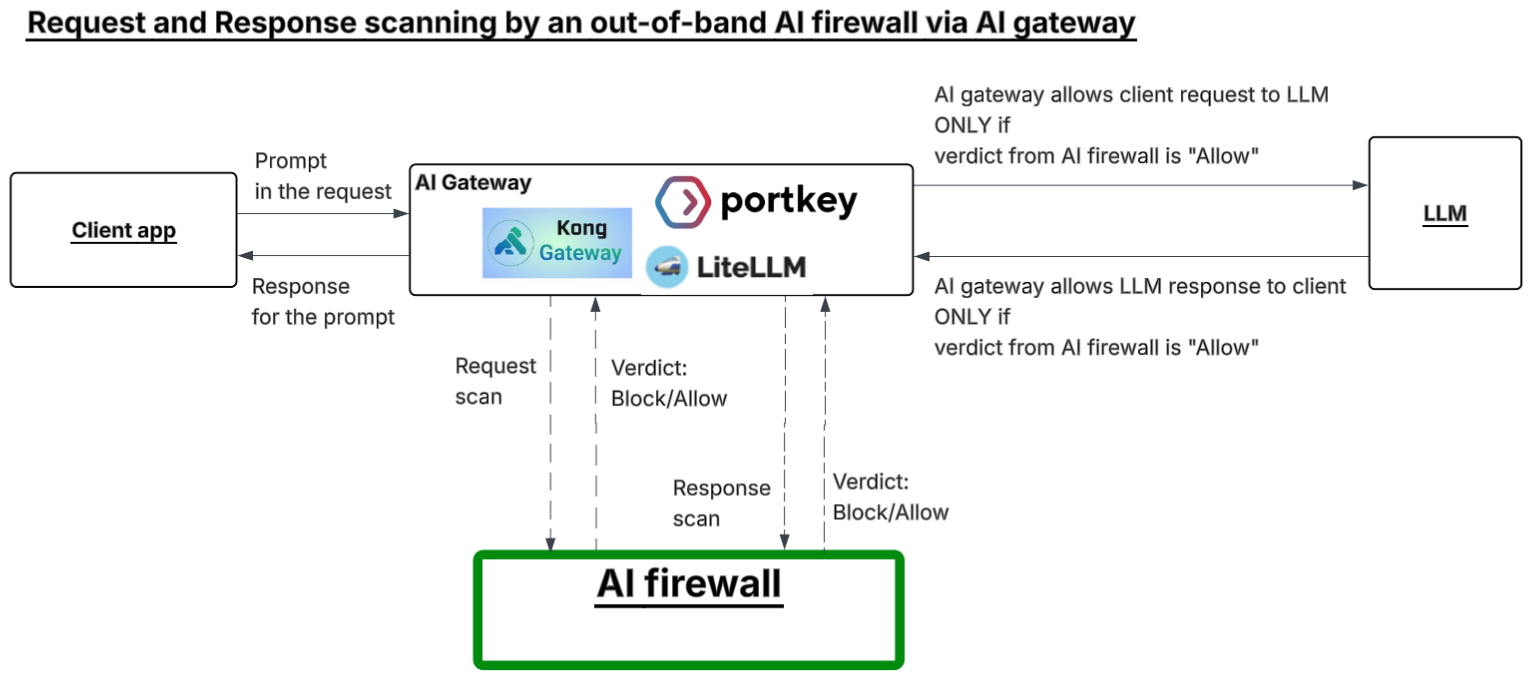
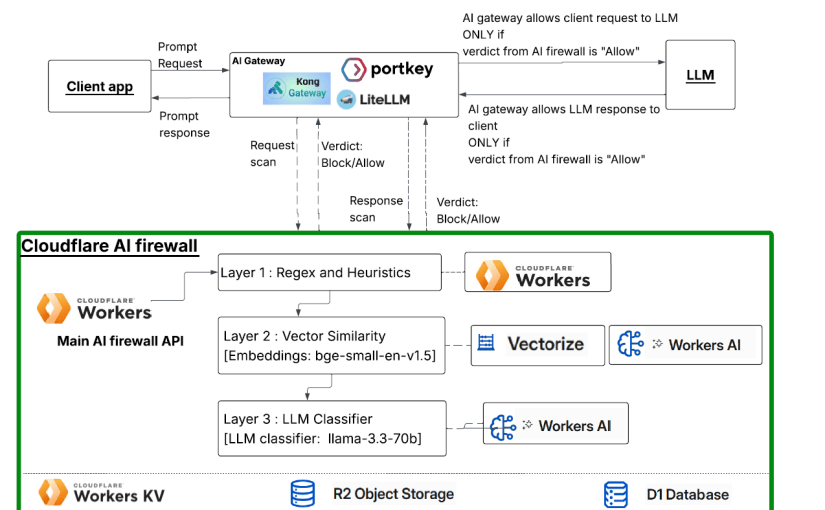
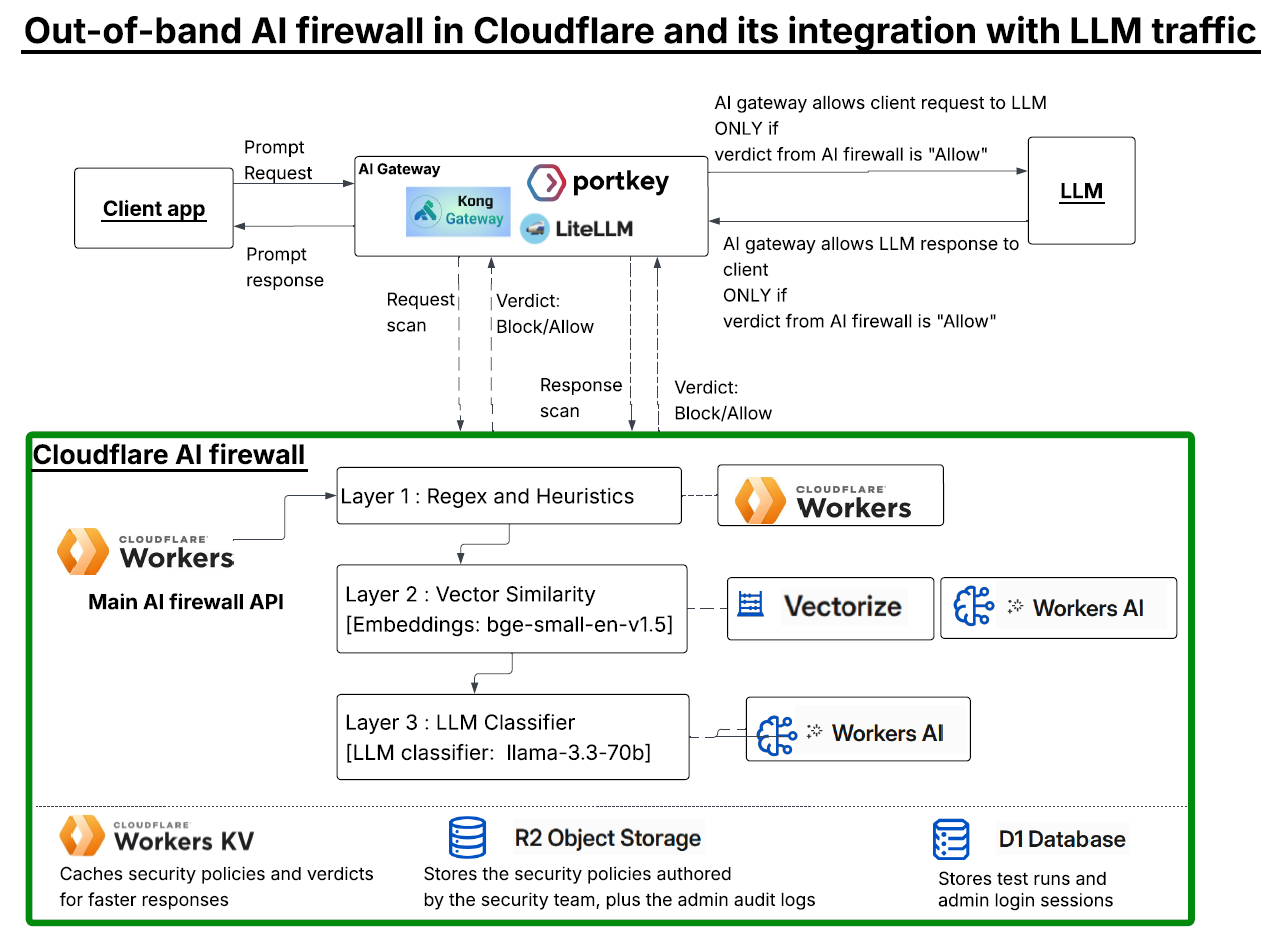
The diagram shows how it fits. Your model access still runs through your existing AI gateway, whether that is Kong, Portkey, LiteLLM, or whatever you already have. But before a prompt reaches the LLM, the gateway sends it to the AI firewall for a scan. The LLM’s response gets scanned the same way on the way back.

The key part is that the firewall is not inline. It does not sit in the traffic path and it does not block anything itself. It just returns a verdict, Blocked or Allowed, and the gateway enforces it. If the request is allowed and the response is allowed, traffic flows. If either one is flagged, the gateway stops it.

Where Cloudflare’s AI security sits today

While learning about AI firewalls in general, I really wanted to leverage Cloudflare because of its massive scalability and ability to handle traffic. It runs one of the largest networks in the world, within 50 milliseconds of most of the planet, which makes it an ideal place to run security inspection close to the request.

Cloudflare has three things that sound like they cover it. None of them quite do.

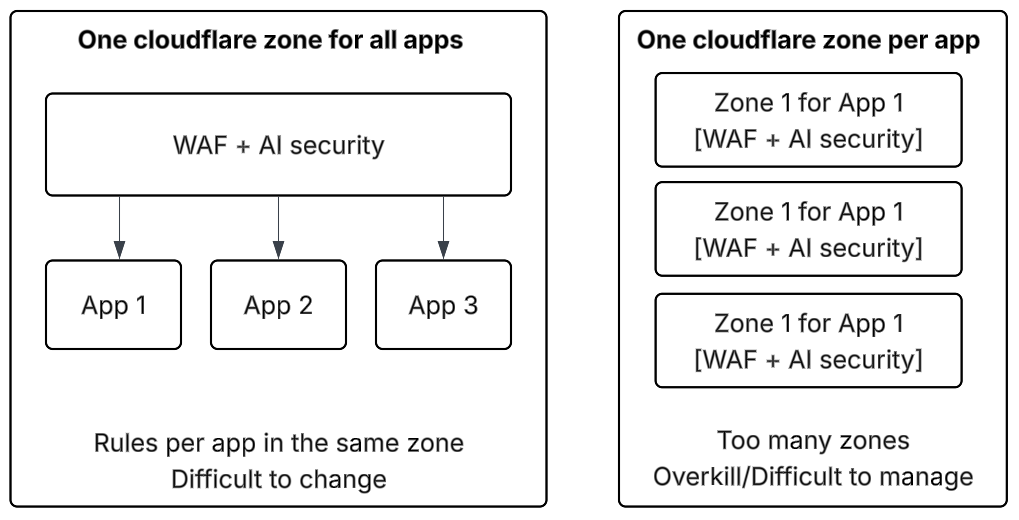
AI Security for Apps AI Security for Apps lives in the WAF. The WAF binds to a zone, which is a domain. Policy is per zone, not per app. So you either share one policy across every app, or you spin up a zone per app and manage all of them.

https://developers.cloudflare.com/waf/detections/ai-security-for-apps/

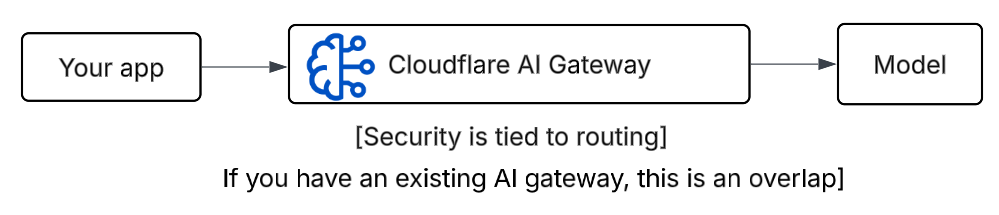
AI Gateway AI Gateway inspects only what you route through it. It is an inline hop, the same shape as Kong, LiteLLM, or Portkey. If you already run one of those, the Cloudflare gateway competes for that slot.
https://www.cloudflare.com/products/ai-gateway

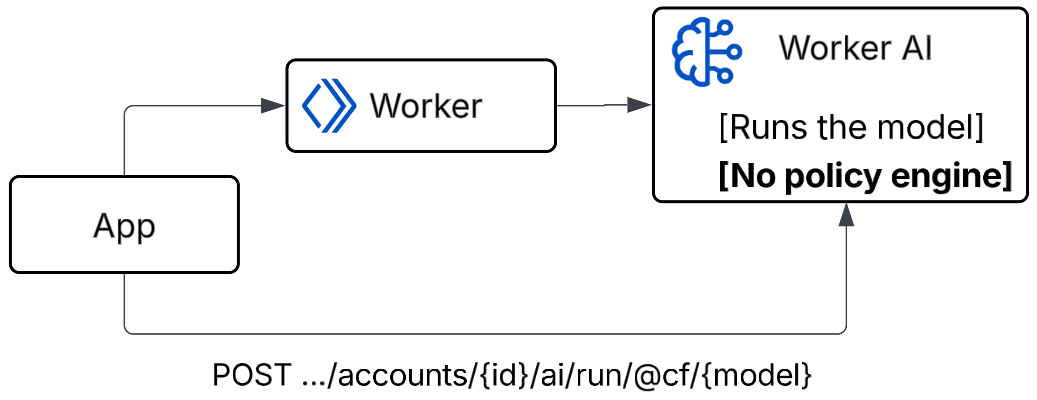
Workers AI just runs a model at the edge. But there is no inbuilt policy engine to inspect the prompt and hence verdict.
https://www.cloudflare.com/products/workers-ai/

All three assume the same thing: your AI traffic already flows through Cloudflare on its way to the model. But if you already run a gateway like Kong, Portkey, or LiteLLM, that is where you want to enforce the decision, and none of these can give you a verdict to enforce.

That is the gap. There is nothing in Cloudflare’s stack you can point your gateway at and ask, is this prompt safe?

Should you build your own AI firewall?

It’s always a build vs buy decision. I would argue in this case.you should buy, because it’s somebody else’s responsibility…

Why did I built this AI firewall then?

To demonstrate Cloudflare could build one too with their own infra components.
Also, becuase I can. 🙂

What did I build

So I built the missing piece, entirely on Cloudflare’s own primitives, to show the platform already has everything it needs.

It is three Workers:

firewall-api is the inspection endpoint. You send it a prompt with an API key, it runs the detection pipeline, and it returns a verdict. This is the out-of-band API your gateway calls.

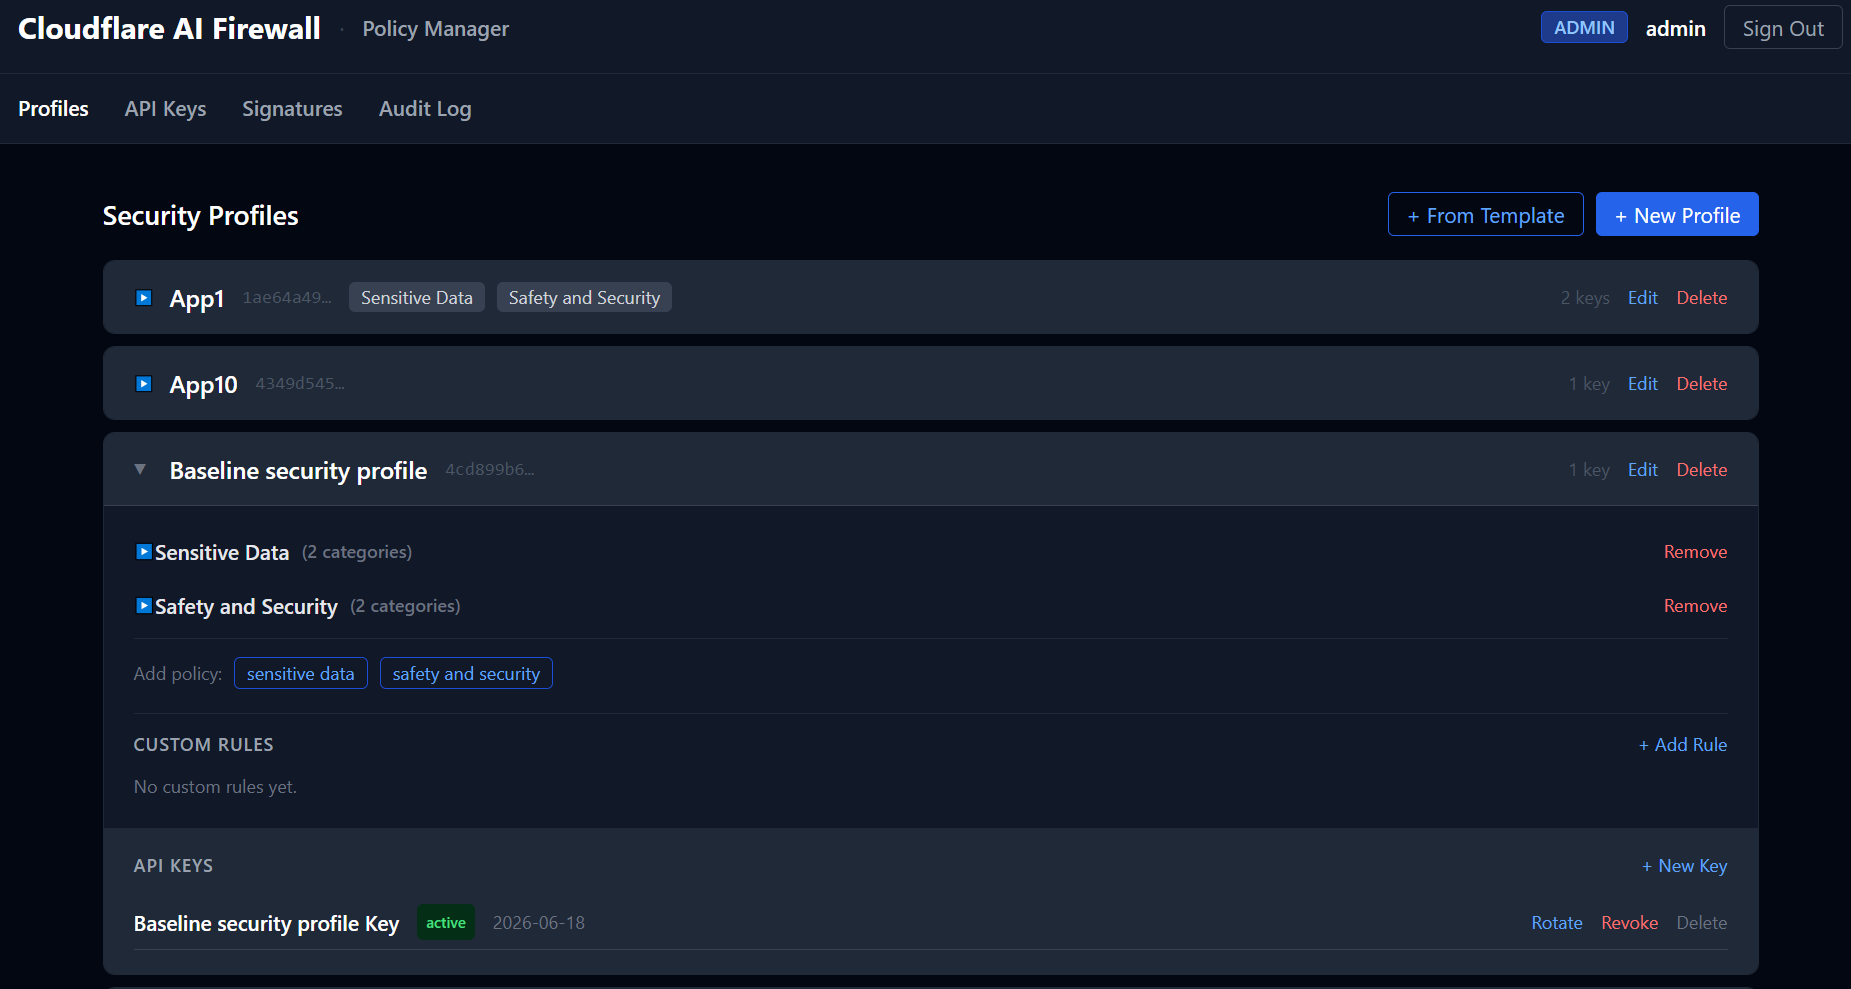
policy-manager is the admin side. A REST API and UI for managing security profiles, API keys, and attack signatures. This is where you decide what each tenant’s firewall actually checks for.

firewall-tester is a test runner. A UI that fires curated prompt sets at the firewall and charts the results, so you can see what passes, what gets blocked, and why.

Everything runs on Cloudflare. KV for fast policy and verdict lookups, R2 for durable policy storage and audit logs, D1 for test history, .Vectorize for attack signature matching, and Workers AI to run the embedding model and the classifier. No outside services. That is the point. If a single developer can wire this together from parts Cloudflare already ships, it is a product Cloudflare could offer natively.

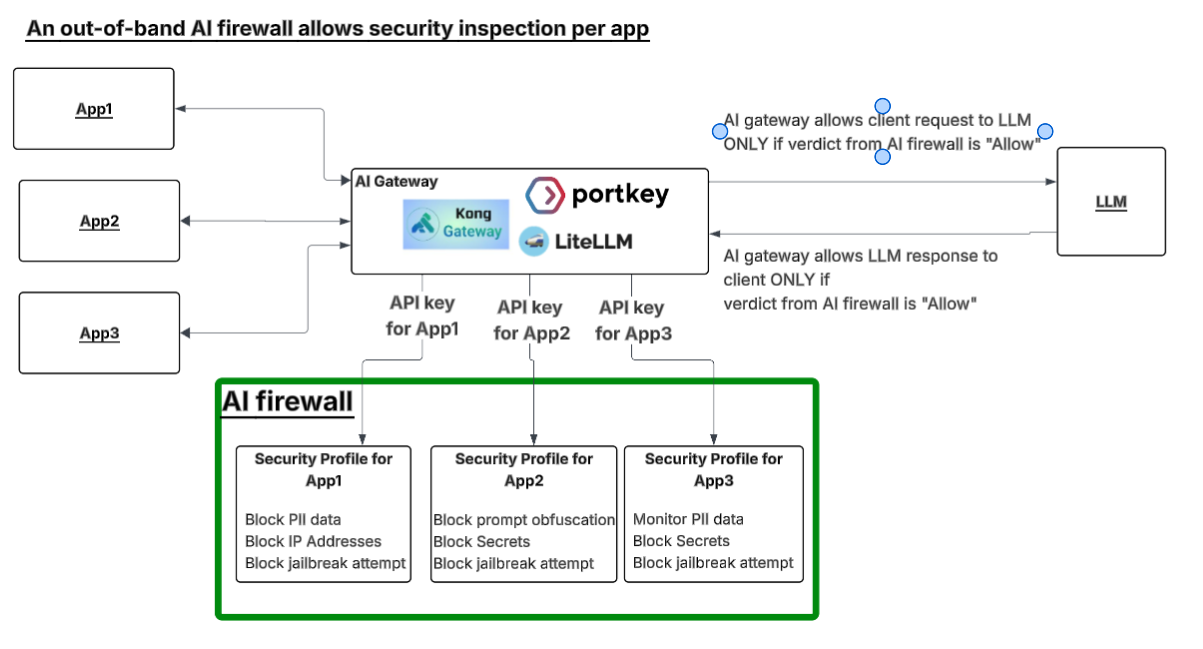
One firewall, one policy per app

This is where the out-of-band model earns its place. Every app gets its own API key. The gateway sends that key, the firewall loads that app’s profile, and runs its policy. One endpoint, one engine, a different policy per caller.

The diagram shows three apps, three profiles, behind one gateway. App3 is the interesting one: it monitors PII instead of blocking it, so you get full visibility into PII in its prompts without stopping a single request. That is how you watch a detection before you enforce it.

Adding an app is issuing a key and attaching a profile. No new WAF rules, no new domain, no zone. Policy lives with the key, not the network path.

The detection pipeline

This is the most important part of an AI firewall. Everything else is plumbing. How well it inspects a prompt decides whether the firewall is worth running.

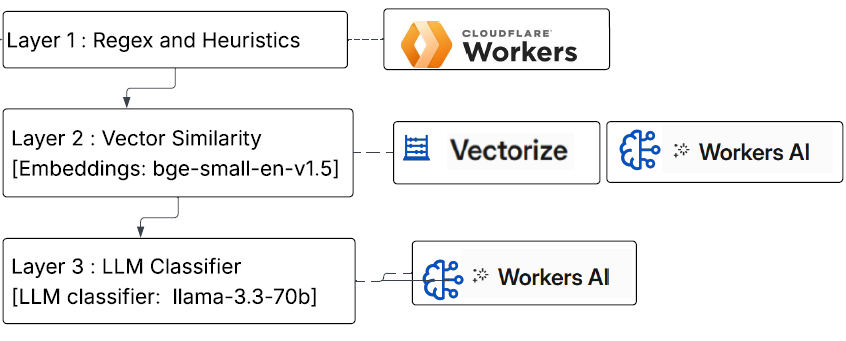
It does not run one big check. It runs three checks, ordered cheapest to most expensive. It stops as soon as it has an answer.

Layer 1: heuristics. Regex for known patterns: injection phrases, jailbreaks, PII, obfuscation. This runs in the Worker. There is no model call, so it is fast and runs first. Regex matches patterns, not intent. Expect some false positives. A researcher quoting an attack as an example can trip it.

Note : If this prompt was judged before, return the stored verdict. I use two tiers. The Workers Cache API comes first, since it is colocated in the same datacenter. Workers KV is the cross-region fallback. Repeat traffic resolves in milliseconds.

Layer 2: vector similarity. Attackers rarely send a known attack word for word. They reword it. I embed the prompt with bge-small-en-v1.5 on Workers AI and compare it against known attack signatures in Vectorize. A reworded injection still matches when the regex missed it.

Layer 3: the LLM. This is the expensive check. I use llama-3.3-70b-instruct-fp8-fast on Workers AI to read the prompt for meaning. It catches novel threats that match no pattern and no signature. It costs seconds, not milliseconds. So it runs last, and only when the cheaper layers cannot decide.

The value is in the overlap. Each layer catches a different kind of miss. Most threats get caught by at least one of them. None of this is 100 percent. A determined attacker will find an edge eventually. This should run as one control among others, not the only thing between a prompt and your model.

This is one approach and it works. It can be better. The layers, the thresholds, the models, all of it is worth tuning. I would rather ship something honest and keep improving it than pretend it is done.

If you find this interesting, please feel free to check out the github repo:

https://github.com/ashishmgupta/cloudflare-ai-firewall
Screenshot : The policy manager